
Do you want to know, How to Learn Large Language Models (LLMs)? If yes, read this article and find a step-by-step roadmap on How to Learn Large Language Models (LLMs).
So you want to learn large language models, and you’ve probably noticed the advice out there is all over the place. One blog says you need a PhD in math. Another says just learn to prompt ChatGPT and you’re done. Both are wrong, and following either one wastes months.
Let me give you the honest version. I build LLM applications, and I teach this on my YouTube channel: RAG systems, LangChain apps, running models locally with Ollama, building agents with LangGraph. I’ve walked thousands of people through this exact path. So this isn’t a roadmap I pulled from a press release. It’s the order I’d actually tell a friend to follow if they wanted to go from zero to building real LLM projects in 2027.
By the end of this guide you’ll know exactly what to learn, in what order, which free video or course to use at each step, how to know you’re ready to move on, and how long the whole path really takes. Let me start with the short answer, then walk you through every step.
How to Learn Large Language Models (LLMs)?
- Step 1: Get Comfortable With Python
- Step 2: Learn Machine Learning and Deep Learning Foundations
- Step 3: Understand How LLMs Actually Work
- Step 4: Learn Prompt Engineering
- Step 5: Start Building With LLM APIs and LangChain
- Step 6: Learn RAG (Retrieval-Augmented Generation)
- Step 7: Learn Fine-Tuning (LoRA / QLoRA)
- Step 8: Build AI Agents
- Step 9: Deploy, and Keep Learning
How Do You Learn Large Language Models? (Quick Answer)
To learn large language models in 2027, follow this path: get comfortable with Python, learn the basics of machine learning and neural networks, then understand how transformers and LLMs actually work. From there, learn prompt engineering, start building with LLM APIs and LangChain, then move into the two skills real jobs want most: RAG (Retrieval-Augmented Generation) and fine-tuning. Finish by learning to build agents and deploy what you make. You do not need a PhD or heavy math to start. You need Python, curiosity, and a habit of building small projects as you go. For most people it takes two to four months of consistent practice to get genuinely job-relevant.
Now let me unpack all of that, because the order and the “why” are where people go wrong.
The LLM Learning Roadmap at a Glance
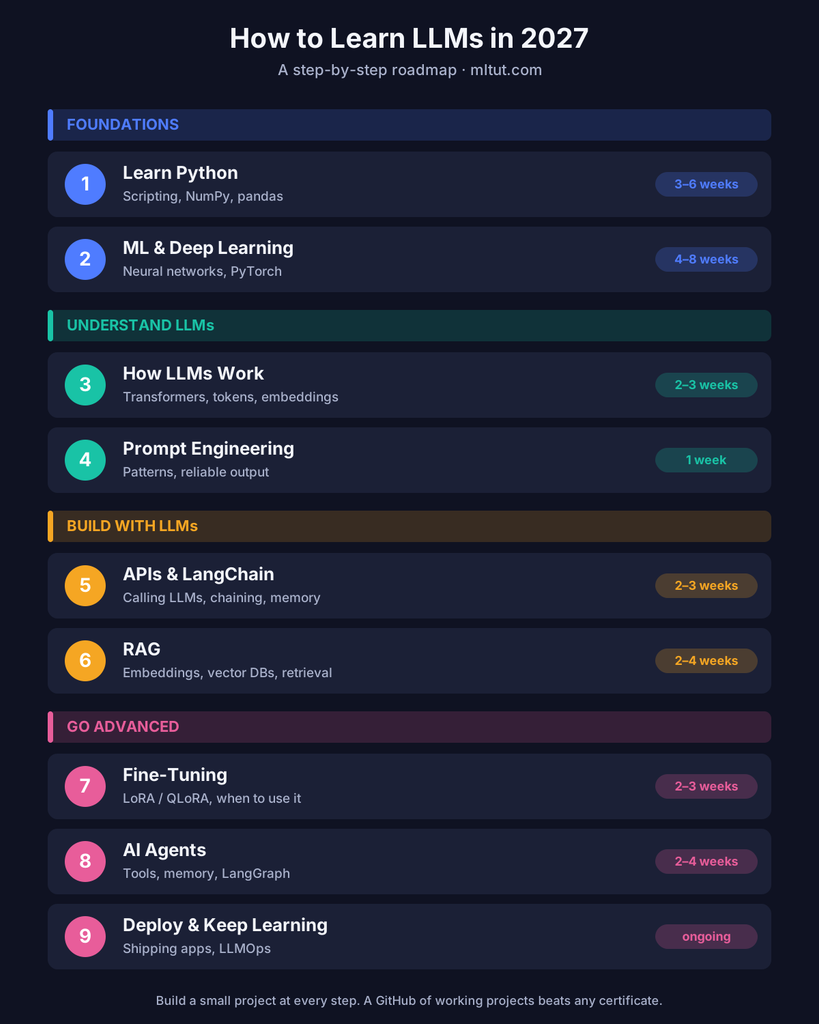
How to learn large language models (LLMs) step-by-step roadmap 2027 The LLM learning roadmap at a glance: 9 steps, from Python to deploying your own AI apps.
This is the whole path in one view. Each step builds on the last. The times assume a few focused hours a week and that you already have the previous step down.
| Step | What you learn | Time | Where to start |
|---|---|---|---|
| 1. Python | Scripting, NumPy, pandas | 3-6 weeks | Python for Everybody (Coursera) |
| 2. ML & Deep Learning | Neural networks, PyTorch basics | 4-8 weeks | Deep Learning Specialization (Coursera) |
| 3. How LLMs work | Transformers, tokens, embeddings | 2-3 weeks | Generative AI with LLMs (Coursera) + my LLM video |
| 4. Prompt engineering | Prompt patterns, reliable output | 1 week | Prompt Engineering for ChatGPT (Coursera) |
| 5. Build with APIs & LangChain | Calling LLMs, chaining, memory | 2-3 weeks | LangChain Bootcamp (Udemy) + my LangChain videos |
| 6. RAG | Embeddings, vector DBs, retrieval | 2-4 weeks | My RAG videos + LangChain course |
| 7. Fine-tuning | LoRA/QLoRA, when to use it | 2-3 weeks | Finetuning LLMs (Coursera) + my RAG vs Fine-Tuning video |
| 8. AI agents | Tool use, memory, LangGraph | 2-4 weeks | My LangGraph videos + agent courses |
| 9. Deploy & keep learning | Shipping an app, LLMOps | Ongoing | LLMOps (Coursera) |
Keep this table handy. The rest of the guide teaches each row properly, so you understand the concept before you spend time or money on it.
What Are Large Language Models (LLMs)?
A large language model is an AI system trained on enormous amounts of text to understand and generate human-like language. You give it words, it predicts what should come next, and because it has read a staggering amount of text during training, those predictions turn into coherent answers, essays, code, translations, and more.
The models you’ve heard of are all LLMs: GPT-4 and GPT-5 from OpenAI, Claude from Anthropic, Gemini from Google, and open-source models like Llama and Mistral. They differ in size, training data, and how open they are, but they share the same core design. What changed between the clunky chatbots of a few years ago and today’s models is mostly scale (far more data and parameters) and one key architecture called the transformer, which I’ll explain in the next section.
LLMs are powerful, but they have real limits, and knowing those limits is half of learning to work with them. They can be confidently wrong (this is called hallucination), they can reflect biases in their training data, and they only “know” what was in that data up to a cutoff date. They don’t look information up the way a database does unless you build that ability in. A big part of this roadmap, especially RAG and fine-tuning, is about working around exactly these limits.
If you want the beginner-friendly version in plain language, I made a video that covers this end to end: What Is an LLM? Everything You Need to Know in 10 Minutes. Watch that first, then come back here.
How Do LLMs Actually Work?
You don’t need the math to start, but a simple mental model helps everything later make sense. This is what actually happens inside an LLM, without the jargon.
First, text becomes numbers. An LLM can’t read words, only numbers. So your text is broken into small chunks called tokens (roughly words or pieces of words), and each token is turned into a list of numbers called an embedding that captures its meaning. Words with similar meanings end up with similar numbers, which is how the model “understands” that king and queen are related.
Second, the model weighs how words relate. This is the clever part, and it’s what the transformer architecture added in 2017. A mechanism called attention lets the model look at every token in your input and decide how much each one should influence every other one. In the sentence “the trophy didn’t fit in the suitcase because it was too big,” attention is how the model figures out that “it” means the trophy, not the suitcase. This ability to weigh context is why modern LLMs feel so much smarter than older systems.
Third, it predicts the next token, over and over. At its core, an LLM is a very sophisticated next-word predictor. Given everything so far, it predicts the most likely next token, adds it, and repeats. Do that billions of times with a model trained on most of the internet, and you get something that can write, reason, and answer questions. The amount of text it can consider at once is its context window, and it’s grown enormously, which is why today’s models can read whole documents.
That’s genuinely most of it. Everything else in this roadmap builds on these three ideas: tokens and embeddings (text to numbers), attention (weighing context), and next-token prediction (generating output).
Is It Hard to Learn LLMs? Do You Need a Degree?
Let me kill the biggest fear right away. No, you do not need a degree, and no, it is not as hard as people make it sound.
Learning to use LLMs well (prompting, building simple apps) is genuinely beginner-friendly and you can start this week. Learning to build with them seriously (RAG, fine-tuning, agents) takes real effort and comfortable Python, but it’s a skill, not a talent. If you can write a Python script and you’re willing to build small projects and learn from what breaks, you can learn this.
What trips people up isn’t the difficulty. It’s the order. They jump straight to fine-tuning a model before they understand what a token is, get overwhelmed, and quit. Follow the steps below in order and the whole subject stops feeling scary.
Prerequisites: What You Need Before Learning LLMs
Before the roadmap, let me be clear about what you actually need first, because this is the part most guides skip and the part people search for most. You don’t need all of this to be an expert. You need enough to not be lost.
1. Programming basics. You should be comfortable with variables, loops, conditionals, and functions. If you’ve never coded at all, start here, it’s a few weeks, not years.
2. Python. Python is the language of AI, full stop. You need to be comfortable with it, including basic libraries like NumPy and pandas for handling data. This is the single most important prerequisite. For a complete, free-to-audit path, Python for Everybody from the University of Michigan on Coursera is the gentlest start, and Python for Absolute Beginners on Udemy is a solid paid alternative.
3. A little math, but less than you fear. You need a working feel for linear algebra (vectors, matrices), basic probability, and the idea of a gradient. You do not need to derive proofs. I built a whole series showing this with code instead of chalkboards, including I Built a Neural Network from Scratch (NumPy Only) and my linear-algebra-with-NumPy videos, which is honestly the fastest way to make the math click without a textbook.
4. Machine learning basics. Understand supervised vs. unsupervised learning, what training and evaluation mean, and what overfitting is. You don’t need to master classical ML, but the vocabulary carries into everything LLM-related.
That’s it. If you have Python and the willingness to learn the rest as you go, you’re ready.
The Step-by-Step Roadmap to Learn LLMs in 2027
I’ve ordered these so each step builds on the last. At each one I teach the concept first, then give you the related course, a free video from my channel, a time estimate, and a clear signal for when you’re ready to move on. Do the steps in order. Build a small project at each one. Don’t just watch.
Step 1: Get Comfortable With Python
Everything LLM runs on Python. It’s the default language for AI because of its huge ecosystem of libraries, so before anything else, get to the point where you can write a script, work with data, and not panic at an error message. You’re not trying to become a software engineer here. You’re trying to get fluent enough that the language stops being the obstacle.
Focus on the fundamentals that actually show up in AI work: variables, loops, functions, and then NumPy (for working with arrays of numbers, which is what all ML data really is) and pandas (for loading and cleaning datasets). Skip the deep computer-science rabbit holes for now. You can always go deeper later when you have a reason to.
The best way to learn Python is to use it on tiny projects from day one. Write a script that cleans a messy spreadsheet, or one that tallies word frequencies in a text file. Small wins build real fluency far faster than passively watching lectures.
Best course: Python for Everybody (Coursera, University of Michigan) for a complete beginner path, or Python for Absolute Beginners (Udemy) if you prefer a single paid course.
Time: 3 to 6 weeks for a beginner, less if you’ve coded before.
You’re ready for the next step when: you can write a Python script that loads a CSV file with pandas, does something to the data, and prints a result, without copying every line from a tutorial.
Step 2: Learn Machine Learning and Deep Learning Foundations
LLMs are deep learning, so before you can understand them, you need a working grasp of neural networks: what they are, how they learn, and why they’re so good at finding patterns. Skipping this step is the most common reason people find LLMs confusing later. The LLM is just a very large, very specialized neural network, so the foundation is essential.
Focus on understanding a neural network as a system of connected layers that takes an input, passes it through math with adjustable weights, and produces an output. It learns by comparing its output to the right answer, measuring the error with a loss function, and nudging its weights to reduce that error, a process called gradient descent. You don’t need to implement the calculus by hand, but you should understand this loop, because it’s exactly how an LLM is trained, just at a massive scale.
Then get hands-on with one framework, PyTorch or TensorFlow. PyTorch is the more common choice in LLM work today, so if you’re unsure, start there. Build a tiny model that classifies images or predicts a number. Seeing the training loop run once teaches you more than hours of theory.
Best courses: the Deep Learning Specialization (Coursera, DeepLearning.AI) is the gold-standard foundation. For a faster free start, Intro to Deep Learning with PyTorch (Udacity, free) is excellent, and Deep Learning in Python (DataCamp) keeps you coding the whole way.
Free video from me: to really understand what’s happening inside a neural network, watch I Built a Neural Network from Scratch to Create an Image Classifier (NumPy Only) and How to Make a Neural Network in Python from Scratch. Building one by hand once makes the whole field click. If you want the full deep learning path, I mapped it in my deep learning roadmap.
Time: 4 to 8 weeks.
You’re ready for the next step when: you can explain, in your own words, how a neural network learns from data, and you’ve trained at least one small model yourself.
Step 3: Understand How LLMs Actually Work
Now the main event. Before you build with LLMs, understand the machine, because this is the step that makes everything after it feel obvious instead of mysterious. You already saw the plain-English version earlier. This step is about making it concrete.
Go deeper on the transformer architecture and the attention mechanism: how a model processes all the tokens in your input at once and weighs how they relate, rather than reading left to right like older models. Understand tokenization (how text is split into tokens and why that affects cost and length), embeddings (how meaning becomes numbers), and the context window (how much the model can consider at once). These five ideas, transformers, attention, tokens, embeddings, and context, are the vocabulary of everything else.
Also learn the difference between pre-training (the expensive process where a model learns language from massive text) and fine-tuning (cheaply adapting that model to a specific task later). Almost nobody pre-trains their own model. Understanding that distinction now saves you from the classic beginner mistake of trying to “train an LLM from scratch.”
Best course: Generative AI with LLMs (Coursera, DeepLearning.AI + AWS) is the single best foundation course for this. It teaches how LLMs work and how they’re used in the real world without drowning you in math. For the full list of options, see my best LLM courses post.
Free video from me: What Is an LLM? Everything You Need to Know in 10 Minutes for the plain-language overview before the full course.
Time: 2 to 3 weeks.
You’re ready for the next step when: you can explain what a transformer, a token, and an embedding are to a friend, and you understand why training a model from scratch is impractical for most people.
Step 4: Learn Prompt Engineering
Before you write a line of app code, learn to talk to these models well. Prompt engineering is the cheapest, fastest-returning skill in the whole roadmap, and good prompting is half of why RAG and agents work later. A well-structured prompt can be the difference between a model that’s useless and one that nails the task.
The core idea is that an LLM does exactly what its input leads it toward, so the way you frame a request shapes the output enormously. Learn the patterns that reliably help: giving the model a clear role and goal, showing it a few examples (few-shot prompting), asking it to reason step by step before answering (chain-of-thought), and specifying the exact format you want back. These aren’t tricks, they’re ways of giving the model the context it needs to do the job.
Practice this with real tasks you care about, because prompting is a feel you build by doing, not by memorizing. The patterns transfer across ChatGPT, Claude, Gemini, and open models, so what you learn here works everywhere.
Best course: Prompt Engineering for ChatGPT (Coursera, Vanderbilt) is the most complete one. For more options, see my best prompt engineering courses post.
Free video from me: prompting leads naturally into context engineering, the newer evolution of it. Watch Context Engineering Explained: Why More Context Doesn’t Mean Better AI after you’ve got the basics.
Time: about 1 week. You can start this one today, even before Python.
You’re ready for the next step when: you can reliably get a model to produce the format and quality you want, and you understand why a vague prompt gives vague results.
Step 5: Start Building With LLM APIs and LangChain
Now you build. This is where it gets fun. You’ll use an LLM through an API (a way to call a model like GPT or Claude from your own code) and start wiring it into real applications with a framework called LangChain, which handles the plumbing so you build apps instead of reinventing wheels.
Start by calling an LLM API directly from Python: send a prompt, get a response, handle the result. Understand the pieces you’re working with, the system prompt (the model’s standing instructions) versus the user prompt (the actual request), and how to manage cost since you pay per token. Then bring in LangChain to do the heavier lifting: chaining several calls together, adding memory so the model remembers a conversation, and connecting external tools so the model can do more than talk.
The goal of this step is your first real app. A chatbot that remembers context, or a tool that summarizes documents you feed it. The moment you have a working app you built yourself, this whole field stops being abstract.
Best course: LangChain with Python Bootcamp (Udemy) is a focused, practical way to learn the framework. Developing Large Language Models (DataCamp track) is the structured, code-along alternative.
Free videos from me: this is where my channel can genuinely carry you. Start with LangChain Tutorial for Beginners: Build Your First AI App, then Learn LangChain by Building an AI Application. Build along with me.
Time: 2 to 3 weeks.
You’re ready for the next step when: you’ve built and run at least one small LLM app with memory, using an API and LangChain, from your own code.
Step 6: Learn RAG (Retrieval-Augmented Generation)
If you learn one advanced LLM skill, make it this one. RAG is the single most in-demand LLM skill in real jobs, because it solves the biggest problem with LLMs: they invent facts, and they don’t know anything that wasn’t in their training data. RAG fixes both by letting a model answer from your documents and data, which is what almost every real company LLM app actually does.
This is how RAG works, and it’s simpler than it sounds. You take your documents, split them into chunks, and convert each chunk into an embedding (those meaning-numbers from earlier). You store all of them in a vector database, which is built to find the chunks most similar to a question. When a user asks something, you embed their question, retrieve the most relevant chunks from the vector database, and paste those chunks into the prompt as context. The model then answers from that real context instead of from memory, so it stops inventing answers and can use information far newer than its training cutoff.
The practical skills here are chunking (how you split documents affects quality a lot), choosing and using a vector database, and wiring retrieval into your LLM call. Get this right and you can build genuinely useful tools. Get the chunking wrong and your app gives confident wrong answers, which is exactly why I made a video on that specific trap.
Best course: the RAG modules inside Generative AI with Large Language Models and the hands-on RAG work in the LangChain with Python Bootcamp cover this well.
Free videos from me: this is the best-covered topic on my whole channel. Start with What is RAG? Retrieval Augmented Generation Explained in Under 30 Minutes, understand the storage layer with Vector Database Explained: Why Your RAG App Gets the Wrong Answer, then build a real one with Build a Local RAG App In 26 Minutes (Ollama + ChromaDB + Flask) and Build a RAG Chatbot That Doesn’t Hallucinate. When you’re ready for the hard parts, Why Your RAG App Fails in Production (And How Agentic RAG Actually Fixes It).
Time: 2 to 4 weeks.
You’re ready for the next step when: you’ve built a RAG app that answers questions from your own documents, and you understand why chunking and retrieval quality decide if it works. This is the single best portfolio project a beginner can show an employer.
Step 7: Learn Fine-Tuning (LoRA / QLoRA)
Fine-tuning is how you adapt a model to your own data, style, and task when prompting and RAG aren’t enough. The key point to understand first: in 2027 you almost never train a model from scratch. You take an existing open model and fine-tune it, which means training it a little more on your own examples so it learns a new style, format, or behavior.
The breakthrough that made this accessible is parameter-efficient fine-tuning, specifically LoRA and QLoRA. Instead of retraining all of a model’s billions of parameters (which needs a data center), these methods train small add-on weights while freezing the rest, so you can fine-tune a capable model on a single modest GPU. That’s why fine-tuning went from a big-lab activity to something you can do yourself.
The most important skill here isn’t technical, it’s judgment: knowing when to fine-tune versus when to use RAG. The simple rule is that RAG is for giving a model knowledge (facts, documents, information that changes), while fine-tuning is for changing a model’s behavior (tone, format, a specialized style). People constantly reach for the wrong one and waste weeks, so get this distinction clear before you spend time here.
Best course: Finetuning Large Language Models(Coursera, DeepLearning.AI) is a focused primer, and the Udemy AI Engineer Core Track: LLM Engineering, RAG, QLoRA, Agents by Ed Donner covers QLoRA hands-on.
Free video from me: before you spend time fine-tuning, watch RAG vs Fine-Tuning: Most People Pick the Wrong One. Picking the wrong approach wastes weeks, and this saves you that.
Time: 2 to 3 weeks.
You’re ready for the next step when: you can clearly explain when to fine-tune versus when to use RAG, and you’ve run at least one small fine-tune yourself.
Step 8: Build AI Agents
Agents are the frontier, and they build directly on everything above. An AI agent is an LLM placed in a loop that can reason, use tools, and take actions toward a goal, not just answer once. Where a plain model responds and stops, an agent can decide what to do next, call a tool (search the web, run code, query your RAG system), look at the result, and keep going until the task is done.
The core pattern to understand is the reason, act, observe loop: the model thinks about what it needs, takes an action, observes the result, and repeats. On top of that you add tools (the actions it can take), memory (so it remembers across steps), and sometimes multiple agents with different roles working together. Frameworks like LangGraph give you the structure to build these reliably instead of hoping a long prompt holds together.
Agents are powerful but less predictable than a simple call, so the real skill is adding the right guardrails and knowing when an agent genuinely beats a simpler approach. Start small: build an agent that uses one or two tools to complete a multi-step task, then grow from there.
Best course: for the full picture, see my dedicated best AI agent courses post, which covers the strongest Coursera, Udemy, and Udacity options.
Free videos from me: start with What is LangGraph? Build Your First AI Agent (Locally with Ollama), then build something real with I Built a Deep Research AI Agent with LangGraph. If you’re unsure which tool to use, LangChain vs LangGraph vs LangSmith: Which One Do You Actually Need? clears it up.
Time: 2 to 4 weeks.
You’re ready for the next step when: you’ve built an agent that uses tools to complete a multi-step task, and you understand the reason-act-observe loop.
Step 9: Deploy, and Keep Learning
A model running on your laptop isn’t a project anyone can see. The final skill is getting one small app in front of real users, and building the steady habit of staying current, because this field moves fast.
Learn the basics of deployment: wrapping your app behind a simple API or web front end so someone can actually use it, and the operations side of keeping an LLM app running, monitoring it, controlling cost, and handling failures, which is called LLMOps. You don’t need to be an expert here. You need to be able to ship one app and keep it alive.
For staying current, you don’t need to read every paper. Follow a few good researchers and builders, skim major model release notes, and keep building. The fundamentals you’ve learned, transformers, RAG, fine-tuning, agents, are stable. New models and tools slot on top of them.
Best course: the LLMOps course (Coursera, Duke) covers the deployment and operations side that most learning paths skip.
Time: ongoing, but plan a week to deploy your first app.
You’re ready to call yourself job-relevant when: you have at least one LLM app deployed and reachable online, and a few projects on GitHub that show the skills above.
I hope now you understand how to learn large language models.
Hands-On Projects to Cement What You Learn
Reading a roadmap doesn’t make you an LLM developer. Building does. Here are projects that match the steps above, from easiest to hardest. Do them in order, put each on GitHub, and write up what broke.
- A prompt-powered tool: a summarizer or a writing assistant built purely on good prompting. (After Step 4.)
- A simple LLM app with LangChain: a chatbot with memory. (After Step 5.)
- A RAG app over your own documents: answer questions from your notes, PDFs, or a Notion export. This is the one that gets you noticed. (After Step 6.)
- A fine-tuned mini-model: adapt a small open model to a narrow task you care about. (After Step 7.)
- An AI agent: something that uses tools and takes multi-step actions, like a research agent. (After Step 8.)
Each one is a resume line and a story you can tell in an interview. A GitHub full of working LLM projects beats any certificate, every time.
Important LLM Terms in a Simple Words
You’ll meet these words everywhere. Below is a plain-English glossary so none of them trip you up.
- LLM (Large Language Model): an AI trained on huge amounts of text to understand and generate language.
- Transformer: the neural network architecture behind modern LLMs, introduced in 2017, built around attention.
- Attention: the mechanism that lets a model weigh how much each word relates to every other word in your input.
- Token: a chunk of text (a word or part of a word) that the model reads and writes. You’re billed per token on most APIs.
- Embedding: a list of numbers that represents the meaning of text, so similar meanings have similar numbers.
- Parameter: an internal value a model learns during training. Modern LLMs have billions of them.
- Context window: how much text a model can consider at once, input plus output.
- Hallucination: when a model confidently states something false. RAG is the main fix.
- Prompt engineering: the skill of writing inputs that reliably get good output from a model.
- RAG (Retrieval-Augmented Generation): feeding a model relevant chunks of your own documents at query time so it answers from real sources instead of memory.
- Vector database: a database that stores embeddings and finds the most similar ones fast. The storage layer behind RAG.
- Fine-tuning: further-training an existing model on your own examples to change its behavior or style.
- LoRA / QLoRA: efficient fine-tuning methods that train small add-on weights, cheap enough to run on modest hardware.
- Agent: an LLM in a loop that can reason, use tools, and take actions toward a goal, not just answer once.
LLM Jobs and Salaries: What You Can Do With This
Learning LLMs isn’t just a hobby skill in 2027. It’s one of the most in-demand skills you can put on a resume, because every company that adopted AI now needs people who can actually build with it. Here are the roles this roadmap opens up.
- LLM Engineer / AI Engineer: builds LLM-powered applications, RAG systems, and agents. The most direct destination for this roadmap.
- Generative AI Engineer: a closely related title focused on building generative AI products end to end.
- Machine Learning Engineer (LLM focus): an ML engineer who specializes in LLMs, fine-tuning, and deployment.
- NLP Engineer: works on language-focused AI, now heavily LLM-based.
- AI Research Engineer: more research-leaning, often needs stronger math and sometimes a degree.
On pay, these are among the better-compensated roles in tech because the supply of people who can genuinely build is still thin. In the US, AI and LLM engineer roles commonly advertise in roughly the $120,000 to $220,000+ range, with senior roles going higher. In India, comparable roles often run from about ₹8 to ₹40 LPA depending on experience and company. (Numbers vary a lot by location, company, and experience, so treat these as a guide and check current listings, this is the part to refresh before publishing.)
The reason the pay holds up is simple. Anyone can prompt a model. Far fewer people can build a reliable RAG app that doesn’t hallucinate, fine-tune a model sensibly, or ship an agent that works. That gap is exactly what this roadmap closes.
How Long Does It Take to Learn LLMs?
The honest answer depends on where you start and how consistent you are, but the realistic breakdown looks like this.
- To understand LLMs and use them well (prompting, basic concepts): a couple of weeks of casual learning.
- To build simple LLM apps (APIs, LangChain, a basic RAG app): about one to two months with steady practice, assuming you already have Python.
- To be genuinely job-relevant (comfortable with RAG, fine-tuning, and agents, with projects to show): realistically two to four months of consistent, hands-on work.
- If you’re starting from zero programming: add one to two months up front to get comfortable with Python first.
The people who get there fastest aren’t the smartest. They’re the ones who build a small project at every step instead of collecting tutorials.
Can You Learn LLMs Without Coding?
Partly, yes. You can learn to use LLMs, prompt engineering, and the concepts behind them without writing code, and that alone is valuable for a lot of roles. But to build with LLMs, RAG apps, fine-tuned models, agents, you need Python. There’s no way around it. If you want to go beyond being a power user and actually build, learning Python is step one for a reason.
Common Mistakes People Make When Learning LLMs
I’ve watched a lot of people (including myself, early on) fall into the same traps. Avoid these and you’ll move faster than most.
Starting with fine-tuning. Beginners hear “fine-tuning” and think it’s the first step. It’s one of the last. Understand the model and master RAG first.
Skipping Python to “just learn LLMs.” You can’t build without it. A week of Python saves you months of confusion.
Collecting tutorials instead of building. Ten watched videos and zero projects is worth less than one project you built yourself. Build at every step.
Ignoring RAG. It sounds advanced, so beginners skip it. It’s the most in-demand LLM skill in real jobs and you should learn it early.
Confusing RAG and fine-tuning. RAG gives a model knowledge, and fine-tuning changes its behavior. Pick the wrong one and you waste weeks.
Chasing every new model and tool. The field moves fast, but the fundamentals are stable. Learn those deeply instead of jumping on every release.
Never shipping anything. A project on your laptop is invisible. Deploy one small app so an employer can actually see it.
Best Courses to Learn LLMs (Quick List)
If you want the structured version of this roadmap in course form, these are the ones I’d point you to, all from Coursera, Udemy, Udacity, or DataCamp:
- Foundation: Generative AI with Large Language Models (Coursera, DeepLearning.AI + AWS)
- Prompting: Prompt Engineering for ChatGPT (Coursera, Vanderbilt)
- Building: LangChain with Python Bootcamp (Udemy)
- Going deep: AI Engineer Core Track: LLM Engineering, RAG, QLoRA, Agents (Udemy, Ed Donner)
- Credential: Generative AI Engineering with LLMs (Professional Certificate) (Coursera, IBM)
For the full breakdown of each one, with who it’s for and what you’ll build, read my complete best LLM courses guide.
So, this is the step-by-step roadmap to learn LLMs.
Conclusion
In this article, I have discussed a step-by-step roadmap on How to Learn Large Language Models (LLMs). If you have any doubts or queries, feel free to ask me in the comment section. I am here to help you.
Learning large language models in 2027 isn’t about being a genius or having a PhD. It’s about following the right order and building as you go. Get comfortable with Python, understand how LLMs actually work, then build your way up through prompting, LangChain, RAG, fine-tuning, and agents. The roadmap above is the exact path I’d give a friend, and it’s the one I teach every week.
Pick Step 1, start this week, and build one small project before you move to Step 2. If you get stuck, my YouTube channel has a hands-on video for almost every step on this page, so you’re never building alone.
If you want the video version of this whole journey, RAG, LangChain, local models with Ollama, agents, all of it, come subscribe on YouTube, where I build this out in the open, messy parts included.
All the Best for your Career!
Happy Learning
FAQ
You May Also Be Interested In
Best Resources to Learn Computer Vision (YouTube, Tutorials, Courses, Books, etc.)- 2026
Best Certification Courses for Artificial Intelligence- Beginner to Advanced
Best Natural Language Processing Courses Online to Become an Expert
Best Artificial Intelligence Courses for Healthcare You Should Know in 2026
What is Natural Language Processing? A Complete and Easy Guide
Best Books for Natural Language Processing You Should Read
Augmented Reality Vs Virtual Reality, Differences You Need To Know!
What are Artificial Intelligence Examples? Real-World Examples
Thank YOU!
Explore more about Artificial Intelligence.
Thought of the Day…
‘ It’s what you learn after you know it all that counts.’
– John Wooden

Written By Aqsa Zafar
Aqsa Zafar is a Ph.D. scholar in Machine Learning at Dayananda Sagar University, specializing in Natural Language Processing and Deep Learning. She has published research in AI applications for mental health and actively shares insights on data science, machine learning, and generative AI through MLTUT. With a strong background in computer science (B.Tech and M.Tech), Aqsa combines academic expertise with practical experience to help learners and professionals understand and apply AI in real-world scenarios.